

Reminder: I’m offering a limited-time 50% discount on the annual plan:
Once you claim it, the discount will be applied forever.
Now, with only $5/month, you will have access to:
200+ deep-dive data engineering articles
practice-spark: 65 LeetCode-style problems to practice Spark SQL/DataFrame
learn-spark/dbt/airflow: CLI tools to master Spark/dbt/Airflow
If you’re a Vietnamese user, please DM me for an upgrade due to payment issues
Disclaimer: This article is not sponsored by or affiliated with any organization. The intent is not to criticize or undermine either vendor; the benchmark is based solely on my curiosity and observations.
Also, don’t use this benchmark alone to decide whether to use DuckDB or Polars for your needs. Any production tool decision should be based on your context, requirements, and benchmarks designed around your specific use cases.
Intro
Polars and DuckDB have been the obvious choices for many organizations for single-node processing.
They’re performant, easy to use, and easy to set up.
One day, I just thought it would be fun to run both of them on the same dataset to see how they perform.
In this article, I will try to run DuckDB and Polars on datasets of 10GB, 50GB, 100GB, 200GB, and 465 GB.
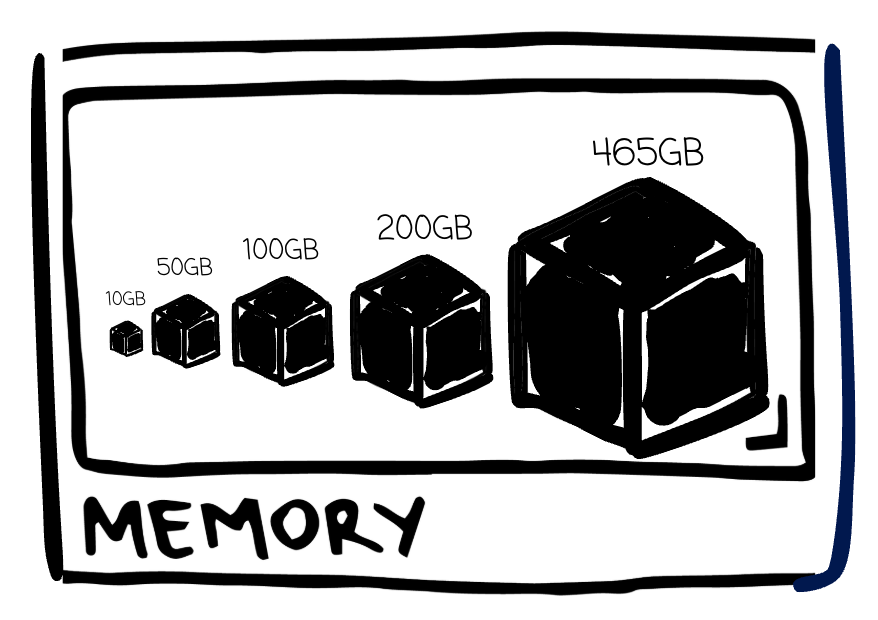
The data volume here is the amount of data in memory; when generating data, the on-disk size will be 3x-4x smaller, since the data will be written in compressed Parquet.
The motivation for the dataset size is that I want to see how DuckDB and Polars perform if the data fits entirely in my laptop's 24 GB RAM (with a 10 GB dataset), then stress test them with a dataset larger than the memory (from 50GB, 100GB, 200GB, to the extreme case of 465GB). Besides speed, I also try to observe reliability (e.g., query failures) and memory usage. All the code is available here.
If you only care about the results and observations, feel free to jump right away to the “Result” section :d
Note 1: This benchmark was run on my laptop, so the results could be very different if it were run on a more isolated machine. Also, there are likely performance tuning techniques for both tools that I'm not aware of, so feel free to share your suggestions in the comments.
Note 2: I asked Claude to help me set up the code for this benchmark. However, all the design decisions and intentions were mine.
Note 3: I run this in the way I like so I’m pretty sure it’s not the standard way to run a benchmark :d
Note 4: This article won’t dive much into DuckDB or Polars. You can check out my previous articles here:


Setup
I ran this on my laptop: an Apple M5 with a 10-core CPU, 24 GB of RAM, and a 1 TB SSD. I also tried to dedicate as many resources as possible to the benchmark; during the run, I closed all other applications.
Python dependencies

First, clone this repo.
Enter its folder and run
uv sync…to install the required Python libraries.
We leverage ibis-bench, the ibis library with utilities for benchmarking across engines such as DuckDB, Polars, and DataFusion.
We use native functions in ibis-bench to generate data and run benchmarks. However, we need a thin wrapper (/src/bench/tuned_run.py) on top of it because there are two shortcomings:
ibis-bench’s own CLI doesn’t have a way to pass DuckDB memory_limit/temp_directory/max_temp_director_size setting.
ibis-bench’s own write_data.py always materializes Polars LazyFrame results using an in-memory engine rather than a streaming engine (given the incompleteness of the Polars streaming engine in the past). With the recent introduction of Polars' new streaming engine, this wrapper attempts to force the Polars data-writing process to use it.
With Polars streaming engine, instead of processing all at once, the data is split into small batches that flow through the query pipeline, rather than the entire table being materialized in memory.
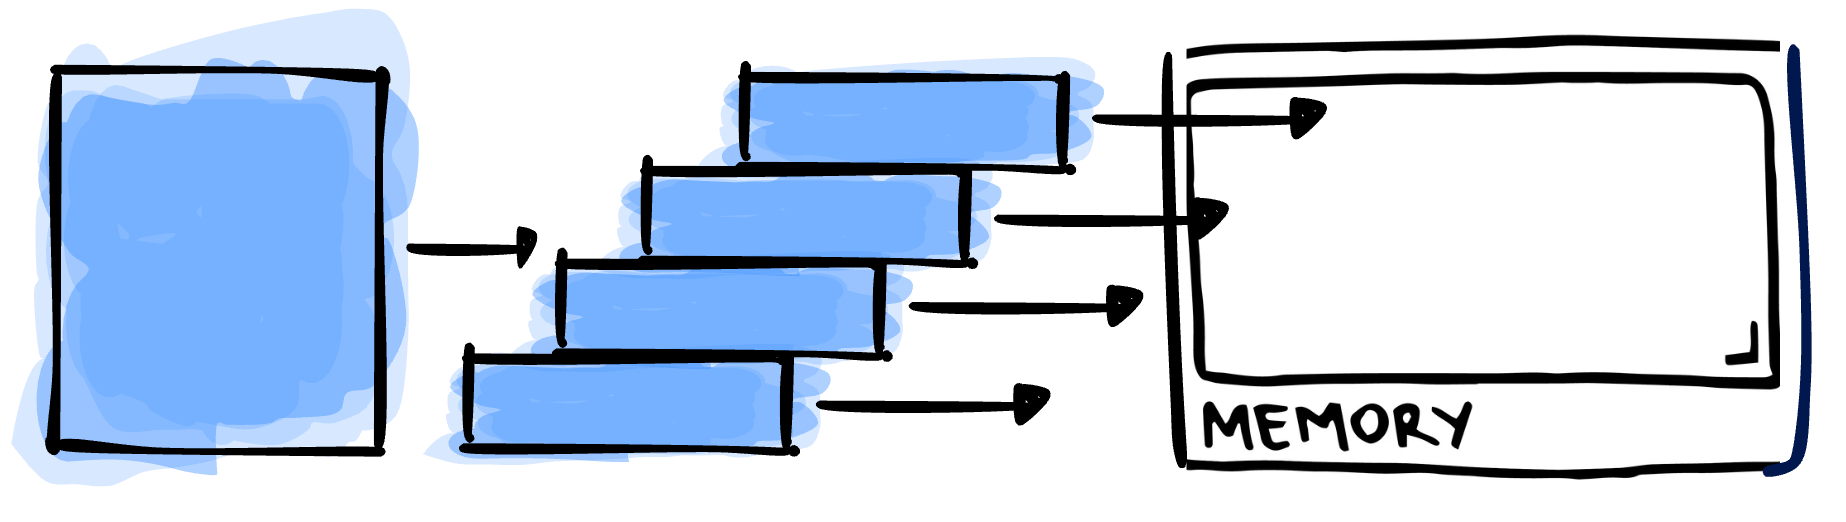
This contrasts with the in-memory engine, which tries to fit the entire dataset into memory.
For DuckDB and Polars, we will use the latest stable versions (at the time of this writing)
dependencies = [
    "ibis-bench==0.2.0",
    "duckdb==1.5.5",
    "polars==1.43.2",
]
The queries
You can view all the queries here.
The ibis-bench library provides 22 tcph queries written in DuckDB SQL and the Polars DataFrame API. Let’s take a brief overview of these queries:
Q1
Pricing summary: revenue, quantity, discount grouped by return status/line status for items shipped before a given date. Full sequential scan + aggregation over all of lineitem (biggest table); simple GROUP BY, no joins
Q2
Cheapest suppliers for a part type/size, in a given region. Multi-way join (5 tables) + correlated subquery; Tests join planning and subquery execution
Q3
Highest-revenue unshipped orders for a market segment. 3-table join + GROUP BY + ORDER BY + LIMIT; tests join + sort/top-N
Q4
Count of orders per priority where at least one line item was received late. Join + correlated EXISTS subquery; tests semi-join / subquery-to-join rewriting
Q5
Revenue by nation for a region within a year. 6-table chain join (customer → orders → lineitem → supplier → nation → region) where supplier and customer must resolve to the same nation; tests the optimizer’s join-order selection across a long join chain, since joining in the wrong order blows up intermediate result size long before the final small GROUP BY
Q6
Total revenue lost to discounts in a date/discount/quantity range. Single-table filter + aggregation on lineitem; tests scan + predicate pushdown, no joins
Q7
Revenue between two nations via suppliers/customers, by year. Self-referential nation join (both supplier and customer nation) + multi-table join.
Q8
Market share of a nation’s suppliers for a part type over time. Large join (8 tables) + conditional aggregation (CASE-WHEN)
Q9
Profit by nation/year for parts matching a name pattern. Large join (6 tables) + string pattern match + GROUP BY on derived year
Q10
Customers with the highest returned-item revenue, by nation. Join + GROUP BY + ORDER BY + LIMIT; similar shape to Q3 but keyed on customer.
Q11
Parts whose total supply value is a significant fraction of a nation’s total. Aggregation + correlated subquery comparing to an aggregate threshold (HAVING against a scalar subquery)
Q12
Correlation between shipping mode and order priority (late shipments). Join + CASE-based conditional counts; tests conditional aggregation.
Q13
Distribution of orders per customer (including customers with zero orders). LEFT OUTER JOIN + GROUP BY + a second aggregation over the first (nested grouping); tests outer join handling
Q14
Percentage revenue from promotional parts in a time window. Join + conditional SUM (CASE) over lineitem/part; tests filtered aggregation.
Q15
Supplier(s) with the highest total revenue in a quarter. View/CTE + join + subquery to find the max; tests subquery materialization and top-N-by-group
Q16
Count of suppliers who can supply parts matching a spec, excluding certain suppliers/complaints. Join + NOT IN / anti-join subquery + COUNT DISTINCT; tests anti-join and distinct aggregation.
Q17
Avg yearly revenue loss from small-quantity orders of a specific part. Correlated subquery computing a per-part average as a filter threshold; tests scalar subquery pushdown.
Q18
Top orders by total quantity, for customers with very large orders. Join + GROUP BY + HAVING on an aggregate + correlated subquery; tests large-order/HAVING filtering.
Q19
Revenue from parts meeting one of several brand/quantity/shipping combinations. Single join with a complex OR-of-ANDs predicate; tests predicate simplification/optimization.
Q20
Suppliers in a nation who over-supply a part relative to half its total shipped quantity. Nested correlated subqueries (2 levels) + anti-join-like filter; one of the most subquery-heavy queries
Q21
Suppliers with late-shipped line items on multi-supplier orders, excluding certain cases. Self-join on lineitem + EXISTS/NOT EXISTS subqueries; tests complex existence checks.
Q22
Customers with no orders in the last 7 years but above-average account balance, by country code. Correlated subquery (avg balance) + NOT EXISTS + string prefix matching; tests subquery + anti-join combo
The experiment
Generate data and run benchmark
Reminder: I’m offering a limited-time 50% discount on the annual plan:
Once you claim it, the discount will be applied forever.
Now, with only $5/month, you will have access to:
200+ deep-dive data engineering articles
practice-spark: 65 LeetCode-style problems to practice Spark SQL/DataFrame
learn-spark/dbt/airflow: CLI tools to master Spark/dbt/Airflow
If you’re a Vietnamese user, please DM me for an upgrade due to payment issues